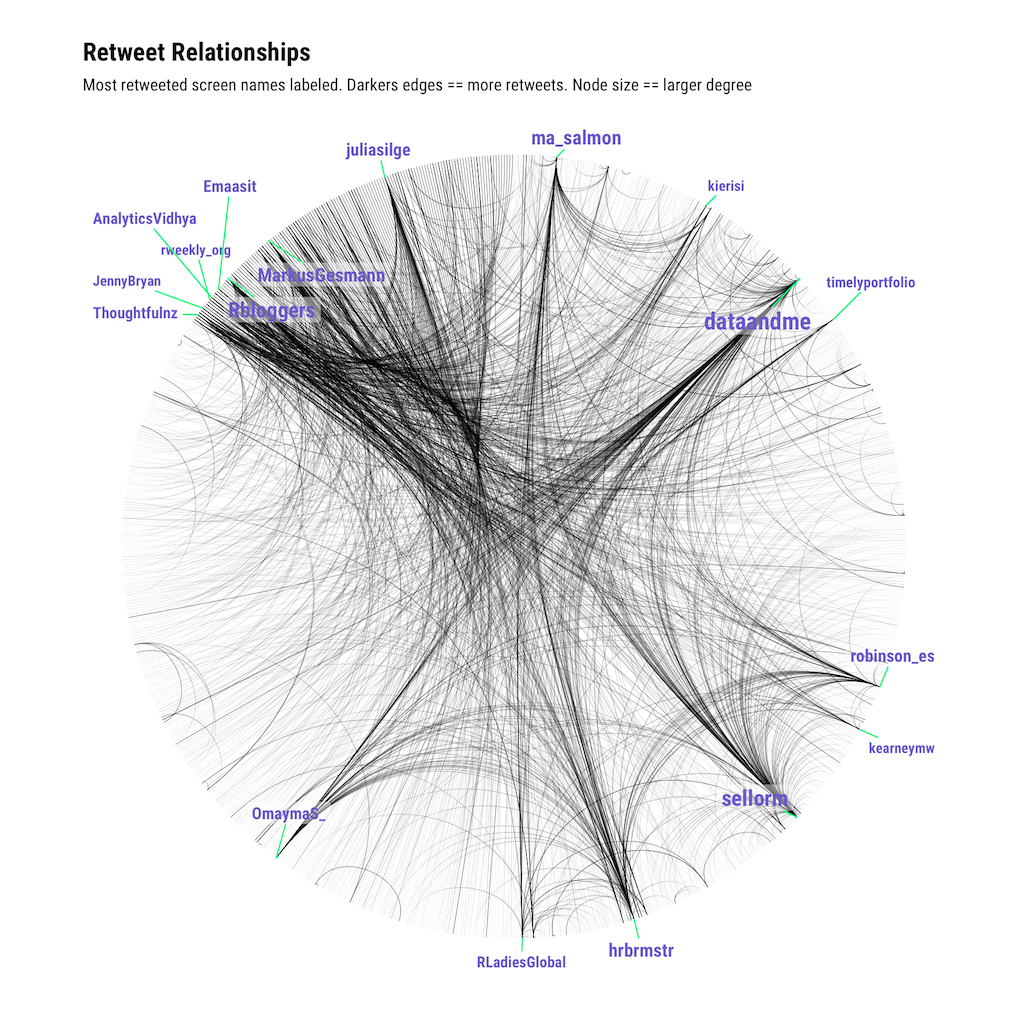
The new year begins with me being on the hook to crank out a book on advanced web-scraping in R by July (more on that in a future blog post). The bookdown? package seemed to be the best way to go about doing this but I had only played with the toy/default examples of it and wanted to test out the platform with a “Hello, World”-like example of a “real” book to iron out issues and avoid more refactoring later on than I know I will have to do. I’ve been on an rtweet kick as of late (I have no idea why) and had an e-copy of O’Reilly’s 21 Recipes for Mining Twitter in the their synced Dropbox folder (it was a free giveaway a few years ago) and decided to make an rtweet version of it in a bookdown project.
You can find the GitHub repo for it here and the rendered version here. NOTE: I will likely not finish the remaining two chapters (I need to spend the time on the real book :-) but will gladly add you as a co-author if you shoot over a PR.
I began with Sean Kross’ quick start and decided to work primarily in Sublime Text and use a Makefile to manage the build process. Since the goal was to iron out kinks for a real production book, here’s a bullet list of some tips as a result of figuring out what worked for me:
- Get Yihui Xie's book. I have a physical copy but having either will help you when things get frustrating (and they do get frustrating at times)
- Use
git. However you instantiate the project, usegitsource control so you don't lose your hard work. However some directories are not tracked ingit! You may want to modify the line with*.rdsin.gitignoreto be a bit less brutal if you happen to generaterdsfiles outside of the project but use them in chapter examples. Also, make sure to put other, sensitive items (like.httr-oauth) in that.gitignoreto avoid having to reset credentials. - Use a
Makefile. I like RStudio, but have far more editing tools in Sublime Text for book-ish work. Plus it has an easy build system manager, and I find it easier to navigate files. - Make liberal use of code chunks. Chapter 16 has a structure that I used in many of the chapters. One block for
library calls(no caching); load fonts (hidden, and primarily for PDF rendering); named, cached logical sections that go with the flow of the chapter text; custom figure dimensions to ensure they come out as desired. Caching will speed up rendering time immensely. - Use saved data and a mixture of
echo=FALSE, eval=TRUE,echo=TRUE, eval=FALSEfor things you generated outside of the book source code (because they may be long running things you don't want to wait for even once in rendering) but want to show in the book (perhaps with slightly modified source). - Despite using
git, create a daily compressed archive of the directory tree and stick it on Dropbox (that can be part of theMakefile). Your work is valuable and you need to make sure it's backed up. - Learn about references. Yihui Xie's book shows how to deal with in- and cross-chapter references, read and use them!
- Use a
bookdown::word_document2vs PDF and make a custom Word template for it. The default PDF output is fine for basic things, but you'll want to generate a better one from Word. - When things stop rendering properly save your recently edited files and go back in time with
gitto a working start. This happened to me a few times as I worked across different machines.gitmakes glitches almost stress free. - Use
rsyncfor publishing. I need to add this to theMakefilebut one, short command-line call can publish your work in seconds to a web server.
I’ll likely have more tips as the year goes on and will have a follow-up post for using web server access logs to generate “kindle-like” reading statistics for your tomes.
No comments yet.